Oct 17, 2026
The Numbers That Kept Me Awake
What AI adoption tells us about the next decade of business and education, and what it does not
Reading Time:
18 min read
Category:
AI
AI adoption, generative AI, AI agents, business strategy, education, workforce development, Neogogy
I was scrolling through social media recently and came across a video making some audacious claims about how many people are using AI, or not, around the world. It invoked a Google study and offered the sort of numbers that arrive with enough confidence to make further questions seem unnecessary: 69 percent of humanity had never encountered AI, 16 percent used free tools, 0.3 percent paid for it, and only 0.04 percent used autonomous agents. The message was reassuring, at least if you spend much of your time wondering whether everyone else has already moved into the future without you. We are still at the beginning, it said. Almost nobody has started. [1]
It got me down a rabbit hole, and this blog is the result of some sleeplessness caused by those random numbers. I wanted to know where they came from. Then I wanted to know what they actually measured. Eventually I found myself asking a more troublesome question: even if we could count every AI user accurately, would that tell us what we need to know about the next five to ten years?
Here is what I could find so far, what I think is reasonable to estimate, and where the numbers stop being the most interesting part of the story.
The Confidence Was More Precise Than the Evidence
The first difficulty was that the chart did not establish the study it claimed to summarize. Its five categories added to 100.34 percent, and the two categories presented as people not actively seeking AI added to 84 percent, while the caption claimed more than 85 percent. Rounding or overlapping groups might explain some of that, but neither was explained. More importantly, the graphic mixed encountering AI, deliberately using it, paying for it, and delegating to it, as though those were separate populations rather than activities the same person might perform. [1]
Google did report substantial product audiences. At its May 2026 I/O event, the company said AI Overviews had more than 2.5 billion monthly active users and AI Mode had surpassed one billion. Those are useful product metrics. They do not produce a census of humanity divided into colored dots. The same person can appear in both audiences, and seeing an AI-generated search result is not the same as intentionally asking a model to help with a task. [2]
The distinction becomes clearer with ordinary life. Someone can insist that they do not use AI while relying on recommendations, navigation, translation, or fraud screening. In a US Gallup study, 99 percent of respondents reported using at least one of six named AI-enabled products during the previous week, although 64 percent had not initially recognized that use. That is not a global percentage, but it explains why “never encountered AI” is a much harder claim than “did not open a chatbot.” [3]
I do not think the person sharing the chart needed to invent a story for the story to become misleading. It is enough to take a nearby statistic, change what it describes, and allow the confidence of the presentation to do the remaining work. We have become very good at distributing numbers and less disciplined about preserving their meaning.
A More Honest Estimate
The strongest cross-country anchor I found was Microsoft’s September 2026 diffusion report. It places June generative-AI use at 18.8 percent of the working-age population, defined as people aged 15 to 64. That is adjusted telemetry, not a worldwide count of all ages, all providers, or every person who has used an AI tool. Microsoft also acknowledges that expanding its coverage will likely increase measured adoption. [4]
Product disclosures help establish scale. OpenAI reported more than 900 million weekly active ChatGPT users in February 2026. Google reported more than one billion monthly Gemini app users in August. Their audiences overlap, and their definitions and activity windows differ. Adding them together would create a larger number without creating better knowledge. [5] [6]
Taking those limitations seriously, my working estimate is that roughly 18 percent of humanity deliberately uses generative AI in a recent month, with a plausible range of 12 to 25 percent. On a rounded population base of 8.3 billion, that is approximately 1.5 billion people, with a range from roughly one billion to just over two billion. This is an analytical estimate, not a Google finding or a survey confidence interval. [7]
For transparency, my central scenario uses rounded reach benchmarks of one billion for Gemini and 900 million for ChatGPT, subtracts an assumed 550 million shared users, and allows an assumed 150 million additional unique users across other tools and subsequent growth. The result is around 1.5 billion. Those overlap and additional-user assumptions are mine. ChatGPT’s weekly reach is a conservative input to a monthly scenario, not an assertion that its weekly and monthly audiences are equal.
Here is the breakdown I would use, with all percentages referring to humanity as a whole, including children:
Deliberate use in a recent month: about 18 percent, with a range of 12 to 25 percent.
Deliberate use in a typical week: about 14 percent, with a weaker range of 11 to 20 percent.
Personally spending at least US$20 monthly on consumer AI: a conditional central estimate of about 0.8 percent, with a range of 0.3 to 1.8 percent.
Recurring use of a tool-executing, multi-step agent: a very uncertain scenario of about 1 percent, ranging from 0.24 to 3 percent, with human review allowed.
Recurring delegation with limited step-by-step supervision: a narrower scenario of about 0.12 percent, ranging from 0.02 to 0.48 percent.
The payment and agent estimates are substantially weaker than the broad-use estimate. The payment scenario assumes a global personal-payer rate and a share reaching the $20 threshold; company subscriber disclosures and selected US surveys do not directly measure that worldwide population. The agent scenarios use illustrative person counts because no representative global census establishes them. Their apparent precision should not be mistaken for certainty. [5] [8]
Embedded AI exposure is a separate question. We do not have a reliable census of everyone affected by AI, and I would leave the global “never encountered” and unaware-use shares unquantified. Nor should any of these layers be added together. A free user can run sophisticated workflows; a subscriber can use a tool occasionally; an employee can use an agent paid for by the organization.
What these estimates suggest is less dramatic and more useful than the reel. AI is already a billion-scale activity. Deep, dependable delegation is much less widespread. We are not at the beginning of access. We are still early in learning what good use looks like.
The World Average Is Not Your Competitive Environment
If my central estimate is approximately right, 82 percent of humanity did not deliberately use generative AI in the recent month. That sounds like an enormous amount of time to prepare. It can also be a dangerous reassurance.
The denominator includes young children, people with limited connectivity, and people whose daily work involves little digital information. A business does not compete against a random sample of humanity. It competes against particular firms, people, and processes. An educator is preparing students for particular professions, not for the average activity level of everyone alive.
One purchasing team can change the software available to thousands of workers. One person redesigning a support process can affect customers who have never opened an AI application. A small group controlling a platform can change how information reaches millions. Population share tells us how many people are present. It does not tell us how much influence they exercise.
There is an educational version of the same mistake. A student can be ahead of the world’s average use and behind the expectations of the profession they hope to enter. They can also use AI every day and still lack the judgment to notice when it is wrong. Frequency, readiness, and competence are different questions.
This is why I am increasingly cautious about the language of being “early.” Early for what? Buying a subscription? Delegating a consequential decision? Building an institution that can tell the difference between an impressive result and a capable person? The first can happen in minutes. The last requires arrangements we have not yet built well.
The Next Five Years: The Cost Moves Into the Organization
Looking toward 2031, I expect the more consequential division to be between organizations that have accumulated the capabilities to use AI well and organizations that have accumulated subscriptions. This is an expectation about a mechanism, not a prediction of a particular adoption percentage.
Erik Brynjolfsson, Daniel Rock, and Chad Syverson give us a useful explanation in their work on the productivity J-curve. General-purpose technologies require complementary investments in processes, business models, and human capital. Some of those investments are difficult to measure, and their benefits can arrive after the technology itself has been purchased. Their argument helps explain a lag between visible adoption and measurable productivity; it does not guarantee that every expensive rollout will eventually pay off. [9]
Consider a hypothetical team that reduces the time needed to prepare a proposal from two days to two hours. If the team can still approve only five proposals a week, its bottleneck has moved rather than disappeared. If the additional proposals contain errors, the saving in drafting may become a cost in review. If customers receive more polished material but less useful advice, the team has increased production without improving the service.
The technology made one task faster. The organization determines whether that becomes value.
Field evidence supports that distinction. The published customer-support study by Brynjolfsson, Li, and Raymond found 15 percent more issues resolved per hour across 5,172 agents, with larger benefits among less experienced workers. METR’s trial of 16 experienced open-source developers found the opposite result on its particular tasks: early-2025 AI tools made completion 19 percent slower. Different settings, different tools, different work. Neither study supplies a universal multiplier. [10] [11]
My expectation for the next five years is that the cost of producing a first version will continue to fall for many kinds of digital work, while the organizational burden of deciding what deserves attention will become more visible. Review, accountability, and customer understanding may become the limiting resources. The firm that produces the most will not necessarily be the firm that earns the most trust.
That also changes what leadership has to protect. Context accumulated through years of work is not automatically preserved in an AI system. A business can automate a task and simultaneously lose the occasions on which employees learned why that task mattered. If the saving is counted and the learning loss is not, the decision will look better in the budget than it does in the organization.
The Next Ten Years: Who Will Produce the People Who Can Judge?
Looking toward 2036, the question that worries me more is not how many people will use agents. It is where the judgment needed to supervise them will come from.
I have explored this in Where Experts Come From (https://alinvrancila.com/blog/where-experts-come-from). Entry-level work often did two things at once: it produced something useful, and it developed the person doing the work. The junior employee learned through making a first attempt, receiving correction, and gradually understanding what the senior colleague could already see. Removing the first function does not automatically provide an alternative for the second.
There is a possible ten-year problem here. The experienced professional who uses AI well today may be drawing on competence formed before that work was automated. Their success does not prove that the new arrangement will produce equally capable replacements. It may show that the current system is benefiting from expertise it has not learned how to renew.
That is not an argument for preserving every repetitive task. Some repetition teaches very little, and some AI assistance can accelerate learning. It is an argument for identifying the learning function before removing the work that carried it.
A business that wants capable people in 2036 may need to pay explicitly for guided practice that used to happen incidentally. A university may need to provide more consequential, observed work rather than more content. Mentoring, supervised decisions, and correction become investments in the capacity to use automation responsibly, not sentimental resistance to efficiency.
The institutional question is who pays for that formation. A company can benefit from an experienced graduate without having funded their development. A university can produce polished assignments without having established what the student understands. Each institution can appear successful while leaving the other to discover the missing competence. Unless we make that responsibility explicit, the cheaper answer will tend to win over the slower work of forming the person.
Education Has Two Different Productivity Problems
A business usually wants the task completed. Education often needs the learner to complete the task because something happens to the learner in the process. The same shortcut can therefore be useful in one setting and destructive in another.
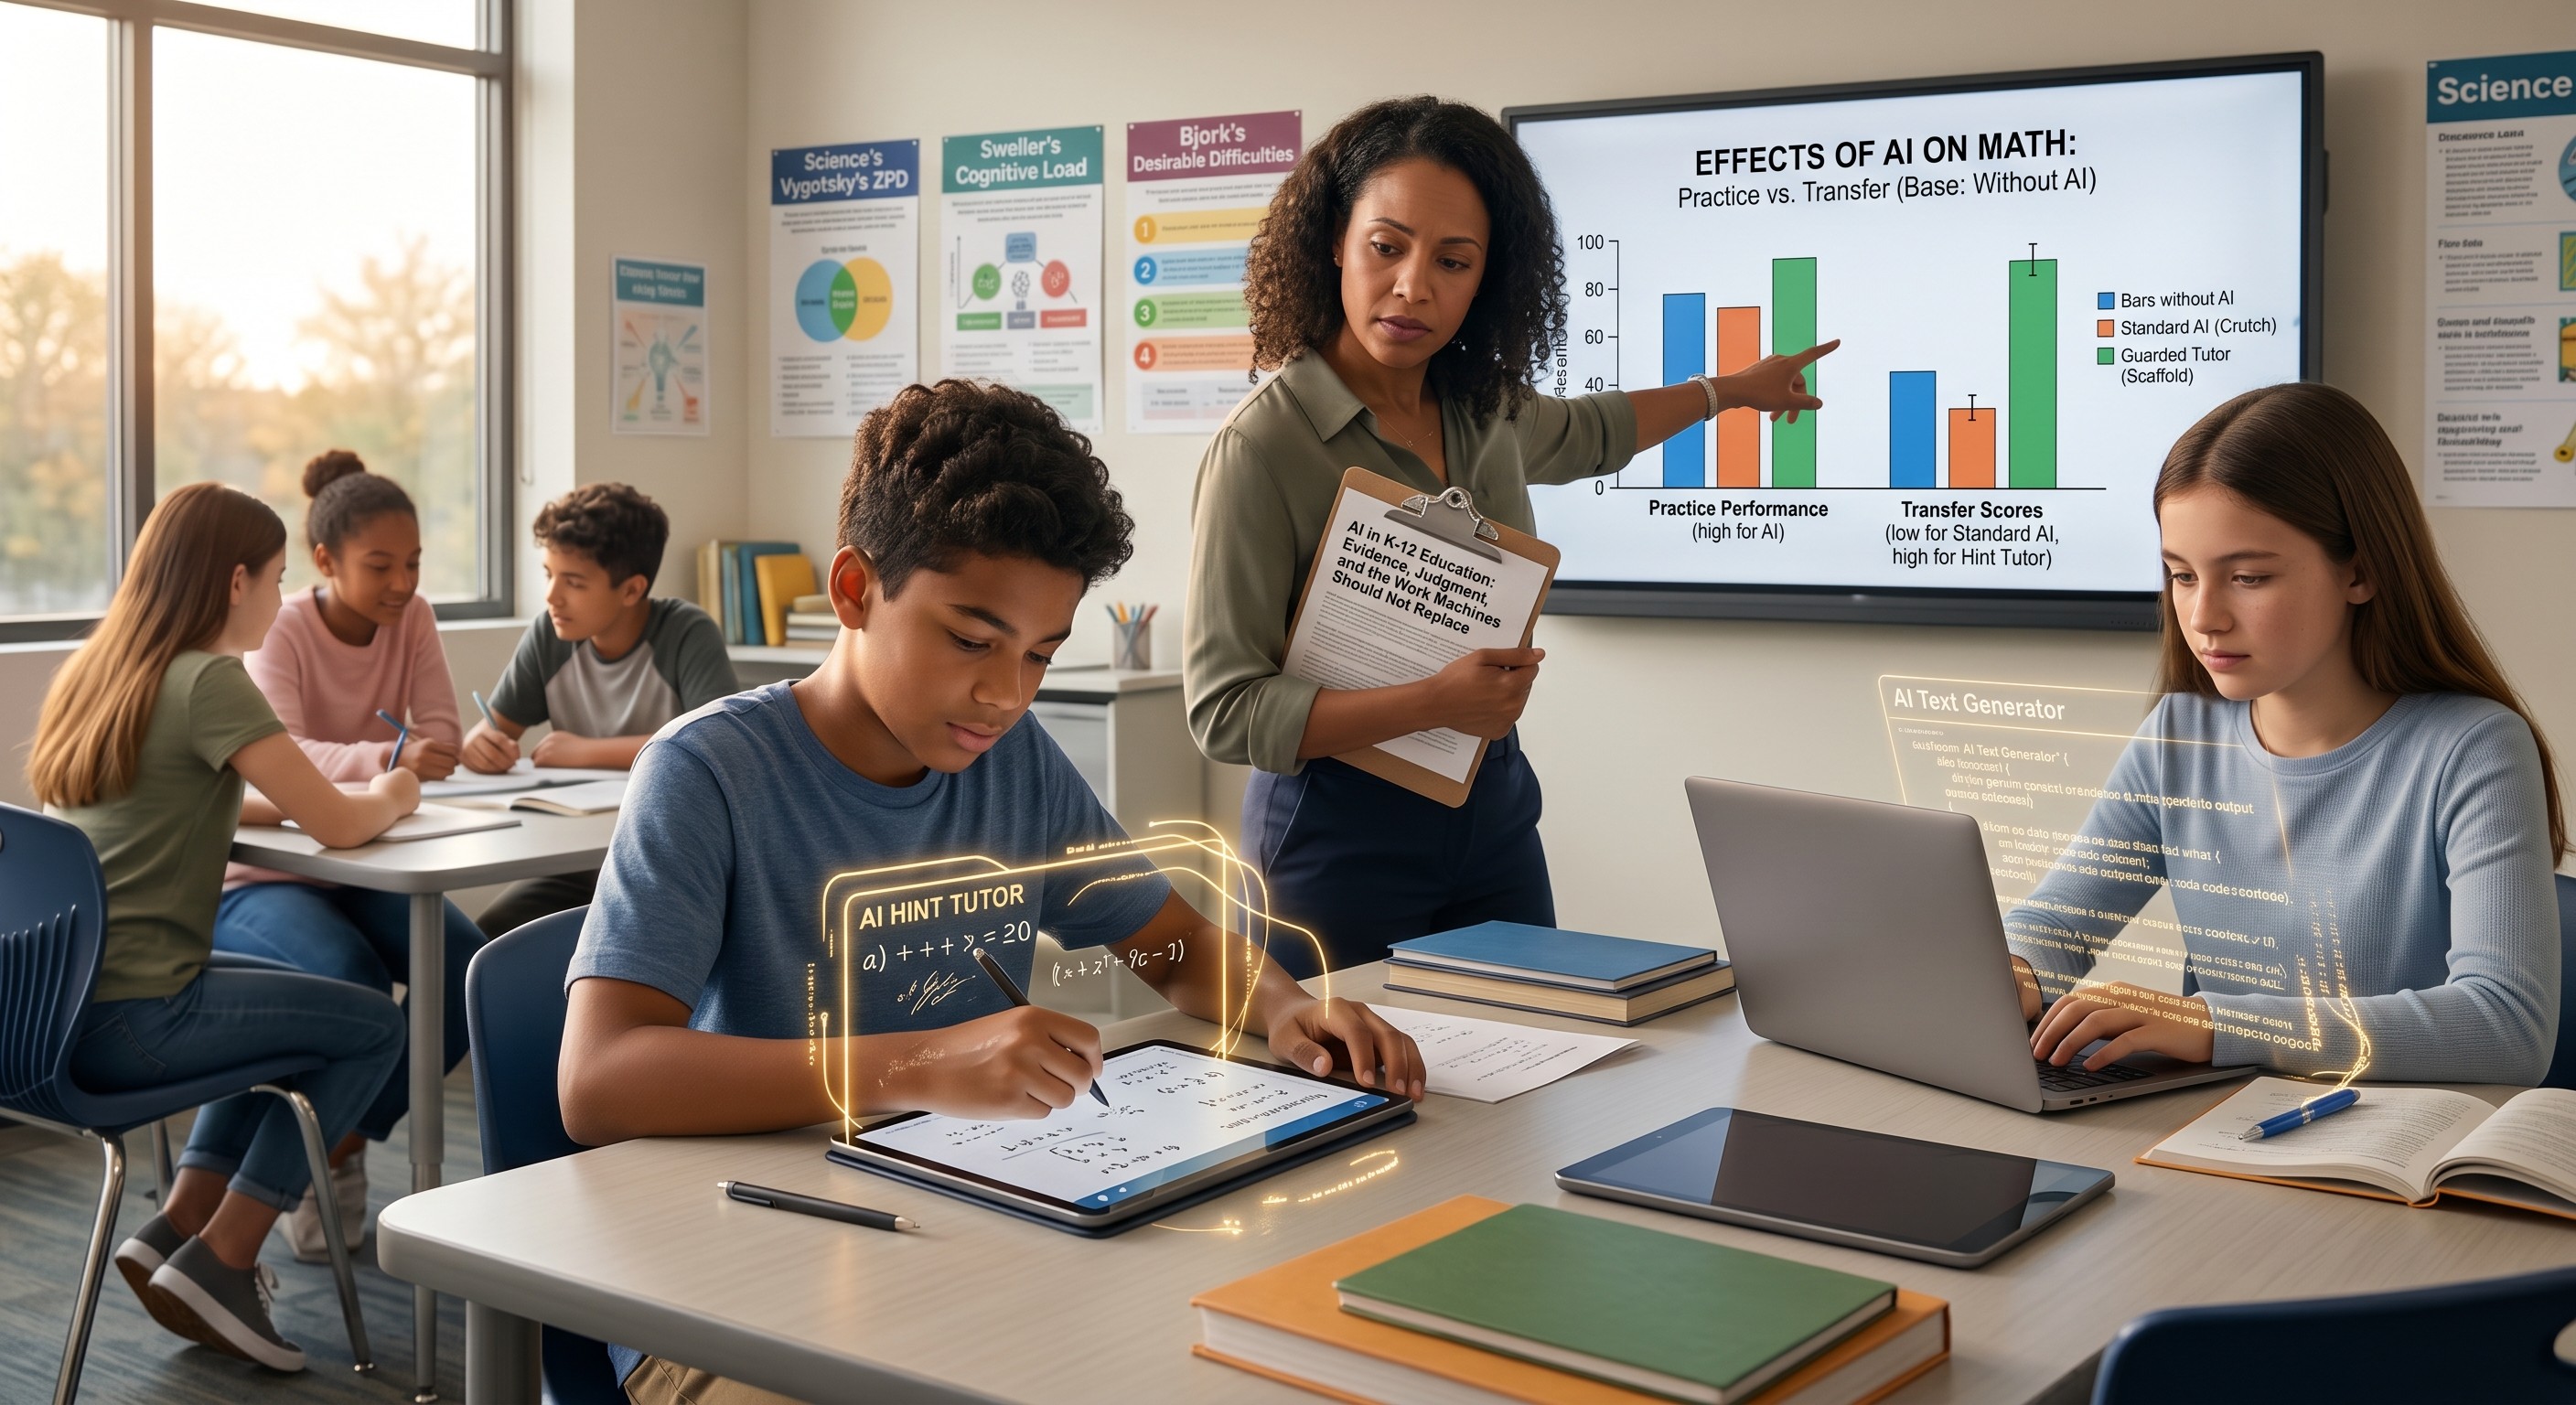
This is not a philosophical objection detached from evidence. In a randomized Turkish high-school mathematics study, unrestricted GPT assistance improved practice performance, but students later scored 17 percent below controls on an unassisted exam. A teacher-designed tutor largely removed that harm, without producing a positive exam effect. In a separate Harvard physics study, an expert-designed AI tutor produced better immediate post-test results than in-class active learning. Both studies concern particular designs and short-term outcomes; neither establishes the long-term fate of students everywhere. [12] [13]
The contrast is instructive. AI can support the work of learning or help the learner avoid it. The difference depends on what the system asks the person to do.
This is part of why I keep returning to Neogogy (https://alinvrancila.com/neogogy). If AI can produce a convincing answer, education must become more deliberate about the human activity around that answer. What did the learner attempt? Which uncertainty did they identify? Could they explain the decision? Can they adapt the idea to a problem that was not in the prompt?
Over the next five to ten years, I expect credible educational assessment to require stronger evidence of process and independent capability. Not because all learning should happen without AI, but because an institution must be able to distinguish assistance from understanding. A graduate should be able to work effectively with the tool, perform important foundational tasks without it, and judge which mode a situation requires.
In Token Legends (https://alinvrancila.com/blog/token-legends-meta-ai-leaderboard), I argued that visible AI activity can become a substitute for the thing an institution actually values. These adoption estimates present the same temptation at a larger scale. Counting users is easier than determining whether they have become more capable. Ease of measurement is not a reason to change the purpose of education.
There is also an uncomfortable equity question. AI could widen access to explanation, translation, and feedback. But an institution that assigns AI-dependent learning without reliable access or human support can turn existing resource differences into educational differences. ITU estimated that 74 percent of humanity was online in 2025; connectivity is still not universal, and a connection does not guarantee an appropriate device, affordable use, or dependable local-language performance. [14]
The risk is not simply that some students will lack AI. It is that some will receive demanding, guided learning with AI while others receive cheap, automated completion and are told that both are personalization. A system can distribute answers broadly while distributing the conditions for understanding very unequally.
The Future Is Not Hidden in the Percentage
I can imagine two plausible outcomes from the same initial adoption estimates.
In one, businesses redesign work so that assistance improves service and employees continue developing judgment. Educational institutions use AI to provide feedback while preserving the student’s responsibility to reason. More people gain access to learning, and institutions become better at demonstrating what their graduates can actually do.
In the other, businesses optimize immediate output while allowing their capacity to evaluate it to weaken. Schools substitute completed assignments for evidence of learning. People become efficient at operating systems whose conclusions they cannot assess, and the organizations that control those systems acquire more influence over everyone else.
Neither outcome requires me to predict the percentage of agent users in 2036. The difference lies in incentives, investment, and what institutions choose to preserve when the machine makes an easier alternative available.
That is where the social-media rabbit hole eventually led me. The reel asked whether most of the world had started using AI. The question I came away with was whether the institutions that have started know what they are trying to produce.
For a business, the answer should be more than additional output. For education, it must be more than completed work.
The numbers may help us locate the present. They cannot relieve us of deciding what kind of people, organizations, and opportunities we want to exist ten years from now. I am curious to hear how you are thinking about that distinction, especially if the pressure to show AI progress is already arriving at your desk.
References
[1] Jack William Instagram reel: the population-chart claims discussed in this essay https://www.instagram.com/reel/DeeE5CpthSR/ [2] Google I/O 2026: AI Overviews and AI Mode product-user figures https://blog.google/innovation-and-ai/sundar-pichai-io-2026/ [3] Gallup, January 2025: Americans use AI in everyday products without realizing it https://news.gallup.com/poll/654905/americans-everyday-products-without-realizing.aspx [4] Microsoft, September 2026: The continued state of global AI diffusion https://blogs.microsoft.com/on-the-issues/2026/09/21/the-continued-state-of-global-ai-diffusion-in-2026/ [5] OpenAI, February 2026: Scaling AI for everyone https://openai.com/index/scaling-ai-for-everyone/ [6] Google, August 2026: More than one billion monthly Gemini app users https://blog.google/innovation-and-ai/products/gemini-app/one-billion-monthly-users/ [7] United Nations: World Population Prospects demographic framework https://population.un.org/wpp/ [8] Menlo Ventures, September 2026: The State of Consumer AI https://menlovc.com/perspective/2026-the-state-of-consumer-ai/ [9] Brynjolfsson, Rock and Syverson: The Productivity J-Curve, working paper 2018, published 2021 https://www.nber.org/papers/w25148 [10] Brynjolfsson, Li and Raymond: Generative AI at Work, published QJE article, 2025 https://academic.oup.com/qje/article/140/2/889/7956298 [11] METR, July 2025: Early-2025 AI and experienced open-source developer productivity https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/ [12] Bastani and colleagues, 2025: Generative AI without guardrails can harm learning https://www.pnas.org/doi/10.1073/pnas.2422633122 [13] Kestin and colleagues, 2025: AI tutoring outperforms in-class active learning https://www.nature.com/articles/s41598-025-97652-6 [14] ITU, Facts and Figures 2025: Internet use https://www.itu.int/itu-d/reports/statistics/2025/10/15/ff25-internet-use/